Jiale Fu
Master's student · Southeast University · PALM Lab
I am a Master’s student at Southeast University’s PALM Lab, advised by Prof. Xu Yang. My research focuses on improving the efficiency of Large Language Models, particularly speculative decoding and efficient attention.
Currently, I work at Moonshot AI’s AI Infra team on MTP optimization for Kimi. I am also a core contributor to EAGLE-4, where I designed and implemented the Efficient LM Head.
Before graduate study, I completed a bachelor’s degree in mathematics at Southeast University, where I was advised by Prof. Wenwu Yu and worked on complex networks.

Research interests Speculative decoding · Sparse and linear attention · Algorithm–infrastructure co-design
News
All updates- EAGLE-4 is available! I am a core contributor and designed and implemented its Efficient LM Head.
- NeurIPS 2026 Spotlight TreeGraft was accepted to NeurIPS 2026 as a Spotlight paper.
- ICML 2026 Spotlight Rethinking LLM Ensembling from the Perspective of Mixture Models was accepted to ICML 2026 as a Spotlight presentation.
- GraphIC: A Graph-Based In-Context Example Retrieval Model for Multi-Step Reasoning was accepted to AAAI 2026.
- Fast Large Language Model Collaborative Decoding via Speculation was accepted to ICML 2025.
Education
Internships




Selected Publications
My highlights-
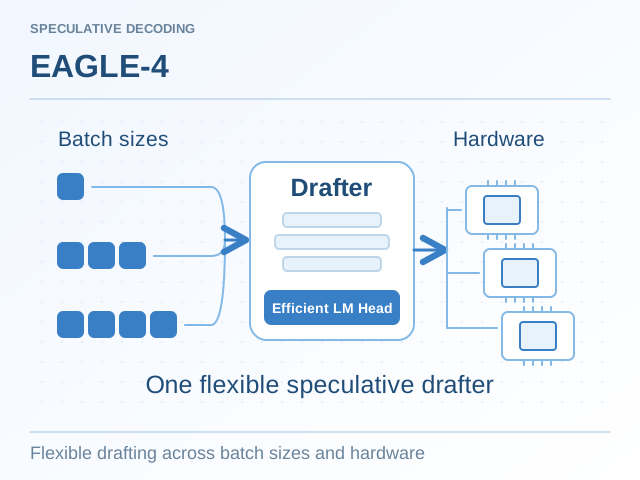
EAGLE-4: One Flexible Drafter for All Batch Sizes and Hardware
Preprint 2026Core contributor to EAGLE-4; designed and implemented the Efficient LM Head and contributed additional architectural improvements that have not been publicly disclosed.
-

Rethinking LLM Ensembling from the Perspective of Mixture Models
ICML 2026 International Conference on Machine Learning

-

GraphIC: A Graph-Based In-Context Example Retrieval Model for Multi-Step Reasoning
AAAI 2026 AAAI Conference on Artificial Intelligence
-
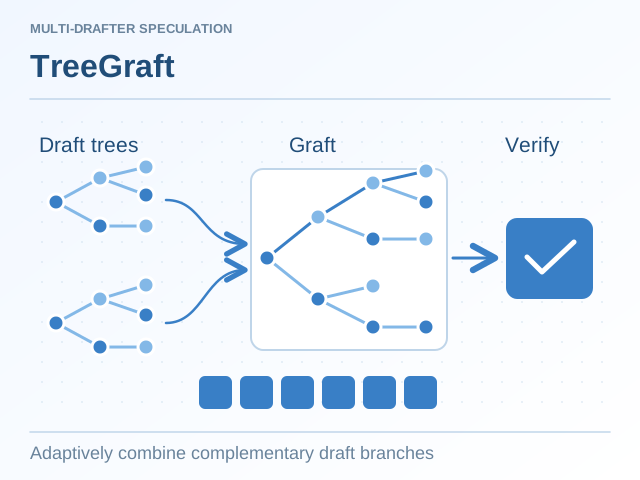
TreeGraft: Adaptive Multi-Drafter Grafting for Tree-Based Speculative Decoding
NeurIPS 2026 Advances in Neural Information Processing Systems

-

Flatter Tokens are More Valuable for Speculative Draft Model Training
ICLR 2026 International Conference on Learning Representations
-

d^2Cache: Accelerating Diffusion-Based LLMs via Dual Adaptive Caching
ICLR 2026 International Conference on Learning Representations
Blogs & Notes
All writingEAGLE-4: Notes on the Efficient LM Head and Earlier Experiments
The two-stage LM Head, frequency-aware SVD, local Top-k, and the experiments behind them.
Technical blog · English translation
DFlash-2's Selector and DSpark's Markov Head: An Equivalence Observation
A shared low-rank transition bias and the candidate truncation behind parallel calibration.
Technical blog · English translation
FlashSpec (Part I): One-Pass Verify-and-Resample for Greedy Drafts
A one-pass method that reduces memory traffic while preserving exact decoding semantics.
Technical blog